Engineering the Agentic AI Scorecard: Measuring Reliability Inside Enterprise Dependability
Runtime Evidence Framework for Measuring Reliability, Governance, Recovery, and Accountability
If an AI agent performs well, can the enterprise prove that its actions were governed, admissible, recoverable, and accountable?
An AI agent can produce the correct answer, select the right tool, and complete its task. Yet successful performance does not establish whether the resulting action was authorized, properly executed, or safe to trust.
The Agentic AI Scorecard addresses this gap by measuring reliability within a broader system of enterprise dependability. It connects agent performance with runtime governance, execution integrity, recovery quality, evidence reconstruction, and human accountability.
Building on Agentic AI Governance: 10 Runtime Controls Before Enterprise Agents Scale and the NIST AI Risk Management Framework, this article develops a multidimensional measurement approach grounded in the Four Runtime Governance Pillars.
The scorecard is not an enforcement mechanism or a single trust rating. It evaluates runtime evidence while recognizing the limits of structural model explainability, evidence quality, and measurement-system reliability. In high-risk settings, runtime evidence should be complemented by explainability methods, safety-case reasoning, and domain-specific validation. The scorecard does not, by itself, resolve structural model opacity.
Reliability makes the agent useful. Runtime evidence shows whether the surrounding system remains dependable.
1. Reliability Inside Enterprise Dependability
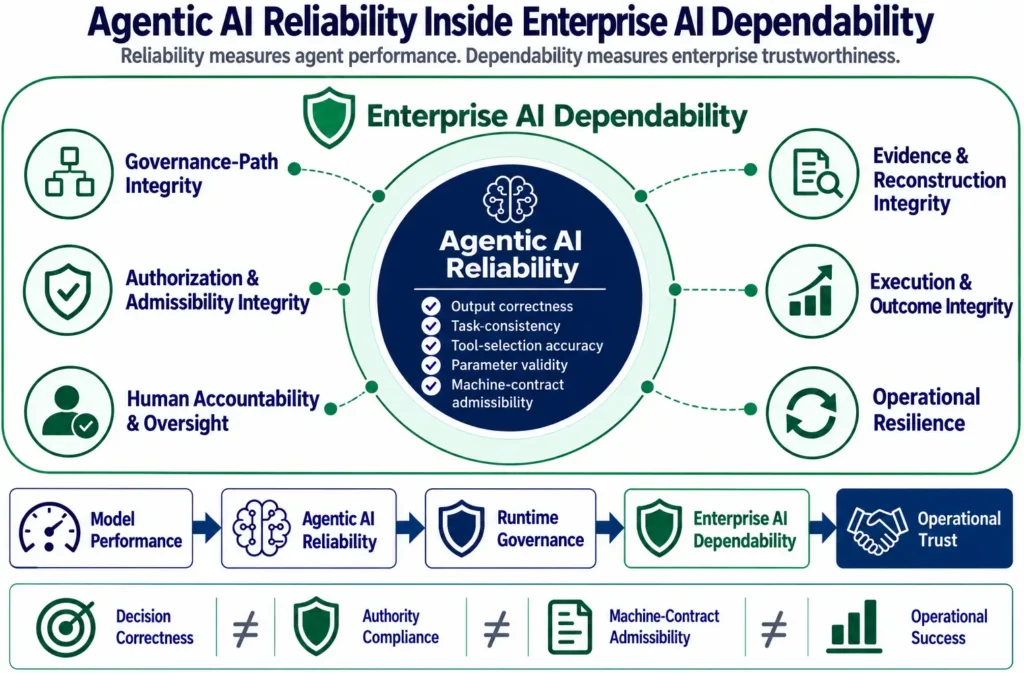
The Agentic AI Scorecard begins with reliability, but reliability represents only one layer of enterprise dependability.
At the agent level, reliability asks whether the system performs its intended task correctly and consistently. This includes output correctness, tool-selection accuracy, parameter validity, task consistency, and machine-contract compatibility.
Enterprise AI dependability asks a broader question: was that performance also governed, authorized, executable, recoverable, and accountable?
Four assurance states must remain distinct:
Decision Correctness ≠ Authority Compliance ≠ Machine-Contract Admissibility ≠ Operational Success
An agent may reach the correct decision without current authority to act. An authorized action may violate an API contract. Even when both conditions are satisfied, downstream execution may produce an unexpected business outcome.
The NIST AI Risk Management Framework similarly treats reliability as one characteristic within broader AI trustworthiness, alongside resilience, security, transparency, and accountability.
Successful task completion therefore cannot substitute for evidence that the action remained legitimate and controlled at the execution boundary.
This distinction becomes especially important in multi-agent systems. Individually reliable agents may interact through shared state, delegated authority, or common evidence sources in ways that produce collectively unacceptable outcomes.
The scorecard must measure both individual performance and the integrity of the surrounding execution system.
2. From the Four Runtime Governance Pillars to Measurable Evidence
The Agentic AI Scorecard depends on evidence generated during governed operation.
The Four Runtime Governance Pillars organize this evidence through three architectural planes:
- Specification & Control: Pillar 1 defines the operating envelope.
- Runtime Decision & Response: Pillars 2 and 3 enforce admissibility and manage intervention.
- Assurance & Learning: Pillar 4 reconstructs evidence, verifies findings, and supports governed improvement.
These planes clarify responsibility without creating additional pillars.
2.1 Pillar 1: Runtime Controls
Pillar 1 defines the approved operating envelope before consequential action. It establishes identities, authority, delegation limits, versioned domain profiles, risk tiers, routing requirements, evidence standards, and execution constraints.
For multi-agent systems, it also defines interaction profiles, concurrency contracts, aggregate-risk limits, and criteria for collective evidence independence.
Representative scorecard signals include policy and control coverage, governance-profile matching, authority and evidence validity, interaction-profile coverage, and control-surface qualification.
Pillar 1 defines the requirements against which runtime behavior can be assessed. It does not itself authorize each specific execution.
2.2 Pillar 2: Execution-Path Enforcement and Admissibility
Pillar 2 determines whether a proposed action may cross a consequential execution boundary under current conditions. Its detailed responsibilities include live admissibility, binding governance dispositions, and decision-bound proof.
The five binding dispositions remain:
PERMIT / REFUSE / CONSTRAIN / HOLD / ESCALATE
Unresolved, stale, contradictory, unavailable, or materially under-represented conditions must never default to PERMIT. They follow the applicable governed disposition path, normally HOLD, REFUSE, or ESCALATE.
Pillar 2 evaluates current authority, policy, evidence sufficiency, execution scope, workflow state, risk, and applicable concurrency constraints.
In multi-agent systems, admissibility must account for both local actions and aggregate effects. Two actions that appear individually permissible may conflict when competing for shared resources or relying on stale state.
Pillar 2 generates and binds the evidence supporting its decision. Scorecard measures include authorization currency, execution-scope continuity, disposition distribution, shared-state validation, and decision-instance integrity.
2.3 Pillar 3: Alerting, Intervention and Recovery
Pillar 3 covers real-time alerting, intervention, recovery, and interpretive support. It detects material changes during governed operation, including authority revocation, stale evidence, execution anomalies, dependency invalidation, shared-state conflicts, and failures affecting governance reachability.
It supports containment, HOLD, escalation, recovery, and renewed admissibility when required. Technical recovery alone does not restore authority. Recovery actions must themselves satisfy current governance conditions.
Representative measures include containment effectiveness, intervention latency, revocation propagation, recovery quality, and dependency invalidation completeness.
2.4 Pillar 4: Reconstruction
Pillar 4 provides the architecture’s assurance and learning function. Its detailed scope covers Decision, Execution, Outcome, Proof, and Reasoning Reconstruction.
It correlates Pillar 1 specifications, Pillar 2 decisions and execution receipts, and Pillar 3 intervention and recovery events to reconstruct what was authorized, executed, observed, changed, and ultimately produced.
Pillar 4 verifies evidence provenance, completeness, independence, execution fidelity, measurement quality, and the limitations of assurance claims.
For the scorecard, it supplies evidence-continuity measures, reconstruction completeness, control-effectiveness findings, and validated improvement proposals.
Importantly, Pillar 4 does not directly change runtime policy. Its findings must pass through Pillar 1’s governed change process before becoming an active operating baseline.
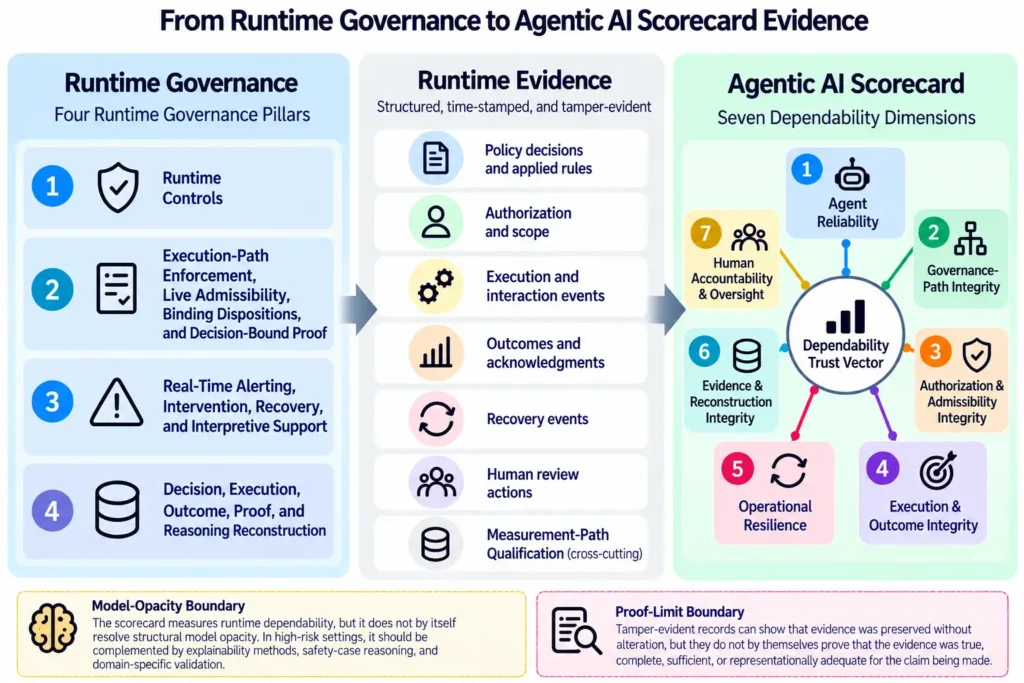
3. The Agentic AI Scorecard: Seven Dependability Dimensions
A dependable enterprise system cannot be adequately represented by one aggregate trust score.
High reliability cannot compensate for invalid authority. Strong authorization cannot compensate for unsafe execution. Complete logging cannot establish that the underlying evidence was truthful.
The Agentic AI Scorecard therefore uses seven separately visible dependability dimensions.
3.1 Agent Reliability
Agent Reliability measures whether the agent performs its intended work correctly and consistently. Relevant properties include output quality, task consistency, tool selection, parameter validity, and machine-contract compatibility.
This dimension establishes operational capability, but not permission to execute.
3.2 Governance-Path Integrity
Governance-Path Integrity measures whether an action enters the correct governance route and reaches the required enforcement surfaces. The route may depend on consequence tier, action family, target system, evidence requirements, or trust boundary.
For multi-agent workflows, it must also account for interaction-profile coverage, agent-to-agent communication, and changes in deployment or trust assumptions. A routing error can undermine otherwise valid downstream checks.
3.3 Authorization & Admissibility Integrity
This dimension measures whether an action retains legitimate, current authority and satisfies applicable execution conditions. It examines authorization currency, delegation scope, evidence sufficiency, decision validity, and execution-scope continuity.
In multi-agent systems, it must also assess shared-state consistency, premise freshness, and cumulative effects. Two individually admissible actions may collectively exceed a risk limit or violate a protected state invariant.
Authority Revocation Propagation Latency is a supporting measure of this dimension, using Pillar 3 evidence to establish whether revocation reached dependent execution within the required interval.
These concerns are particularly relevant to enterprise mutations through The ERP-Agent Bridge.
3.4 Execution & Outcome Integrity
A PERMIT does not guarantee successful execution.
This dimension distinguishes three states:
Authorized Effect → Executed Effect → Actual Resulting State
Measures must detect partial execution, duplicate effects, delayed acknowledgments, inconsistent state changes, and divergence between expected and actual outcomes.
For concurrent agents, actual effect ordering and shared-state conflicts also become relevant. Execution success requires verification of the resulting enterprise state, not merely confirmation that an action was dispatched.
3.5 Operational Resilience
Operational Resilience measures whether the system can contain disruption, assess residual execution state, and recover through an admissible mechanism.
Recovery quality depends on current authority, evidence, state consistency, and the ability to prevent further propagation. Multi-agent resilience also requires invalidating dependent decisions when an underlying state or evidence premise is withdrawn.
Technical recovery does not automatically restore authority or legitimacy.
3.6 Evidence & Reconstruction Integrity
This dimension measures whether material decisions, execution events, interventions, recovery actions, and outcomes can be reconstructed from trustworthy records.
It includes evidence continuity, provenance, non-permit evidence completeness, reconstruction completeness, and interaction lineage.
In collective decisions, agreement among agents does not automatically establish independent corroboration. Multiple agents may rely on the same source or share a common failure mode. Multiple samples from the same model do not, by themselves, establish independent agents or independent evidence.
Tamper-evident evidence demonstrates preservation integrity, not necessarily truth, completeness, sufficiency, or representational adequacy.
3.7 Human Accountability & Oversight
Meaningful oversight requires valid reviewer authority, sufficient evidence, manageable review workloads, and reliable intervention paths.
The scorecard evaluates whether human decisions are attributable, review outcomes are preserved, escalation deadlines are met, and fallback procedures work when reviewers are unavailable. It should also assess whether authorized humans can take over when automated operation becomes unsafe.
Review-engagement indicators should support investigation and workflow improvement rather than serve as automatic judgments of individual performance.
Together, these seven dimensions form a multidimensional trust vector.
Two cross-cutting measures provide additional context:
- Governed-vs-Baseline Delta: How governance changes outcomes under comparable operating conditions.
- Governance Debt: Accumulating unresolved control weaknesses, exceptions, measurement gaps, or operational friction.
Neither becomes an eighth dependability dimension.
4. What Engineers Should Actually Measure
The Agentic AI Scorecard becomes operationally useful when each dimension is connected to observable, interpretable evidence.
The objective is diagnostic measurement, not collecting the largest possible number of metrics.
4.1 Core Scorecard Metrics
| Dependability Dimension | Representative Metrics |
|---|---|
| Agent Reliability | Output Correctness, Task Consistency, Tool-Selection Accuracy, Parameter Validity, Machine-Contract Admissibility Rate |
| Governance-Path Integrity | Routing Accuracy, Route-to-Gate Match Rate, Control-Surface Coverage, Interaction-Profile Coverage, PEP Bypass Attempt Rate |
| Authorization & Admissibility Integrity | Authorization Currency Rate, Execution-Scope Continuity Rate, Disposition Distribution, Decision-Instance Replay-Prevention Effectiveness, Shared-State Validation Coverage |
| Execution & Outcome Integrity | Execution Fidelity Rate, Partial-Execution Rate, Outcome-Verification Completeness, Concurrent-Effect Conflict Rate, Acknowledgment-Resolution Latency |
| Operational Resilience | Containment Success Rate, Residual Impact, Post-Recovery Inadmissibility Rate, Duplicate-Effect Rate, Dependency Invalidation Propagation Latency |
| Evidence & Reconstruction Integrity | Evidence Continuity, Reconstruction Completeness, Execution-Receipt Completeness, Non-Permit Evidence Completeness, Interaction-Lineage Completeness, Collective Evidence Independence Coverage |
| Human Accountability & Oversight | Reviewer-Authority Validity, Escalation-Resolution Time, Review-Outcome Completeness, Review Deadline Compliance, Reviewer-Unavailability Fallback Time |
These are representative engineering measures, not universal prescribed formulas. Each requires an operational definition, observation boundary, denominator, qualification status, and acceptable uncertainty.
Metrics should also be evaluated by action class, domain profile, and consequence tier (T0–T3). Domain and risk tier are separate classification axes.
A single enterprise-wide average can conceal serious weaknesses in high-consequence workflows.
Non-Permit Evidence Completeness deserves particular attention. It measures whether REFUSE, CONSTRAIN, HOLD, and ESCALATE decisions are durably recorded with their supporting evidence and whether relevant timeouts, nonresponses, and capture failures are preserved.
4.2 HOLD Is Not Automatically a Failure
A HOLD indicates unresolved governance conditions, not necessarily an agent failure.
A legitimate HOLD may prevent execution while authority, evidence, workflow state, or risk conditions are clarified.
Useful measurements include:
- HOLD Rate: Frequency of HOLD dispositions.
- HOLD Aging: Time spent in unresolved HOLD.
- Overdue HOLD Rate: Cases exceeding their defined resolution deadlines.
- Eventual Disposition Distribution: Subsequent governed decisions and final execution outcomes.
ESCALATE transfers responsibility to a higher authorized decision path while the proposed effect remains non-executable. It should not be mistaken for completed execution.
Importantly, a later PERMIT does not establish that an earlier HOLD was unnecessary.
The scorecard should distinguish correct protective intervention, unresolved waiting, and independently adjudicated unnecessary intervention.
Review queues should be assessed using tail latency and deadline compliance, not averages alone.
Governance friction and Governance Debt become meaningful when evaluated alongside successful protection and demonstrated control effectiveness.
5. Measuring Recovery, Uncertainty, and Multi-Agent Integrity
Some of the most consequential failures occur after execution begins, when business state may already have changed.
The recovery architecture is examined in Agentic AI Operational Resilience. Here, the focus is measurement.
5.1 Measure Recovery Quality, Not Just Recovery Time
Rapid service restoration does not prove dependable recovery.
A workflow may restart while authority has expired, downstream state has changed, or prior effects remain uncertain.
Five measurements are particularly valuable:
- Containment Success Rate: Whether additional harmful effects were prevented.
- Residual Impact: Committed, partial, uncertain, or inconsistent effects remaining after disruption.
- Post-Recovery Inadmissibility Rate: Technically recovered workflows failing current admissibility checks.
- Duplicate-Effect Rate: Repeated business effects caused by retry or recovery.
- Post-Recovery Evidence Completeness: Reconstructability of residual state, recovery action, revalidation, and outcome.
A checkpoint, rollback, or compensation mechanism may be technically suitable but inadmissible under current policy or authority.
For multi-agent workflows, recovery must also identify affected dependencies, withdraw stale premises, and require fresh admissibility before dependent actions resume.
5.2 Treat Uncertain Execution as a Separate State
A timeout does not prove that execution failed.
An action may have completed while its acknowledgment was delayed, lost, duplicated, or delivered out of order.
The scorecard should track:
- Acknowledgment-Resolution Latency
- Unresolved Execution State Frequency
- Late-Acknowledgment Reconciliation Quality
- Duplicate-Effect Prevention After Uncertain Execution
Acknowledgment-Resolution Latency belongs under Execution & Outcome Integrity. The other measures help diagnose uncertainty and recovery behavior.
This distinction is particularly important for refunds, payments, inventory updates, and other state-changing business operations.
“No acknowledgment” must never be interpreted as “no execution.”
5.3 Protect Decision Instances from Replay
Decision-instance integrity addresses a different problem from ordinary business idempotency.
An idempotency key helps prevent duplicate business effects. A decision-instance identifier or equivalent replay-protection value prevents an already consumed governance permission from being reused.
The relevant metric is:
Decision-Instance Replay-Prevention Effectiveness
Each newly admitted consequential execution must be bound to a fresh decision instance, even when the business action is identical to an earlier one. A consumed PERMIT remains non-replayable; a subsequent authorization requires a new decision-instance identifier or equivalent replay-protection value.
This distinction protects both the integrity of the authorization path and the resulting business state.
5.4 Measuring Multi-Agent Interaction Integrity
Multi-agent environments create failure modes that individual-agent reliability metrics cannot detect.
Several agents may read the same state, independently generate valid proposals, and execute actions that collectively violate a business constraint.
Representative diagnostic measurements include:
- Premise Freshness at Effect: Whether decision-relevant state remained valid through waiting, review, retries, and execution.
- Concurrent-Effect Conflict Rate: Conflicting or collectively prohibited effects observed during concurrent execution.
- Dependency-Retraction Propagation Completeness: Whether invalidated premises reached all materially dependent decisions and actions.
- Collective Evidence Independence Coverage: Whether claimed independent corroboration is supported by sufficiently independent sources and failure modes.
Premise Freshness belongs under Authorization & Admissibility Integrity; conflict rates belong under Execution & Outcome Integrity. Dependency retraction supports Operational Resilience, while evidence independence belongs under Evidence & Reconstruction Integrity.
These are diagnostic measurements within the existing seven dimensions, not a separate multi-agent trust score.
6. Qualifying Measurements and Closing the Improvement Loop
Runtime measurements are useful only when the observation system itself is sufficiently trustworthy.
The scorecard must distinguish operational failure from missing, delayed, distorted, or misclassified evidence.
6.1 Measurement-Path Qualification
A valid metric requires more than an available telemetry stream.
Measurement-path qualification examines whether parsers, validators, evaluators, monitors, recorders, timestamps, acknowledgment channels, and reconciliation processes are sufficiently complete and reliable for the claim being made.
Measurement-Path Qualification is a cross-cutting measurement condition, not an eighth scorecard dimension.
Each material scorecard metric should carry its qualification status, observation coverage, and known uncertainty or limitations.
Missing or unqualified evidence must be reported as unknown or degraded, never silently converted into zero failures or successful outcomes.
Diagnostic investigation should follow a controlled sequence:
Runtime Event → First Operational Deviation → Recovery / Non-Recovery → Measurement-System Check → Failure Phenotype → Root Cause → Governed Change → Validated Improvement
Here, Failure Phenotype describes the observable characteristics of failure, not its established root cause.
The measurement check determines whether the observed deviation reflects the governed process or a defect in observation.
Supporting indicators include Telemetry Completeness, Recorder Availability, Missing-Event Rate, Refusal-Channel Liveness, and Deviation-Localization Success.
In multi-agent systems, the same qualification process must examine shared evidence sources and correlated observation failures.
6.2 Use the Scorecard as a PDCA Feedback System
The Agentic AI Scorecard should support continuous improvement, not merely display operational performance.
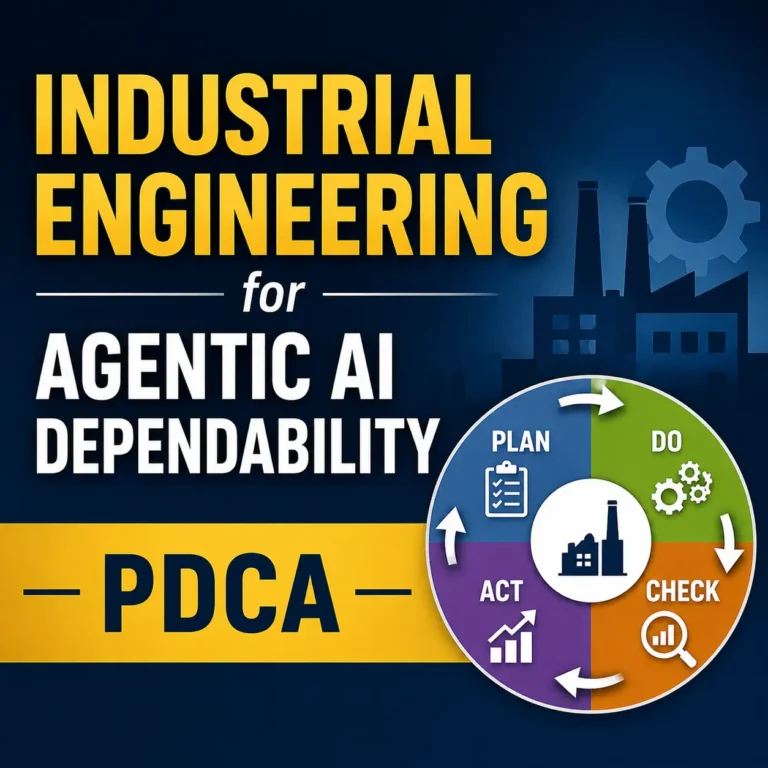
This follows the industrial engineering PDCA approach described in From Theory to the Floor: Applying IE to Agentic AI Dependability.
PLAN → DO → CHECK → ACT
- PLAN: Pillar 1 defines operating limits, domain profiles, evidence requirements, measurement contracts, and recovery conditions.
- DO: Pillars 2 and 3 govern execution, monitoring, intervention, and recovery.
- CHECK: Pillar 4 reconstructs outcomes, qualifies measurements, evaluates control effectiveness, and identifies evidence-bounded findings.
- ACT: Pillar 1 reviews, tests, authorizes, and activates proposed changes before they become a new operational baseline.
After activation, Pillars 2 and 3 operate under the updated baseline, and Pillar 4 verifies whether improvement occurred without unacceptable new failure modes.
A finding does not directly become a new policy.
For significant changes, controlled testing, shadow or canary deployment, activation-epoch management, and rollback requirements help preserve governance continuity.
Before declaring improvement, engineers must verify that apparent gains were not caused by missing events, altered denominators, changed classification rules, or degraded measurement coverage.
Near misses and successful protective interventions should be preserved separately from operational failures. They provide learning evidence without automatically counting correct protective behavior as poor performance.
Cross-cutting measures such as Governed-vs-Baseline Delta, control-induced delay, queue saturation, false alerts, and Governance Debt help determine whether governance improves dependability or merely adds friction.
The objective is validated improvement through governed change, not continuous policy adjustment driven by unverified metrics.
Conclusion: Dependability Must Be Measurable at Runtime
Enterprise agentic AI cannot be judged by task completion alone.
Dependability requires evidence that actions followed the correct governance path, retained valid authority, produced controlled outcomes, recovered safely, and remained reconstructable.
The Agentic AI Scorecard translates those requirements into seven visible dependability dimensions, supported by qualified runtime evidence and risk-sensitive measurement.
Multi-agent interaction, measurement integrity, and recovery quality extend what engineers must observe without changing the scorecard’s fundamental structure.
Most importantly, measurement must lead to validated findings and governed improvement rather than automatic policy changes.
Reliability makes the agent useful. Runtime evidence shows whether the surrounding system remains dependable.